The latest results from the world’s three large listed credit bureaux make one thing fairly clear: the bureau model continues to deliver strong revenue growth and resilient earnings.
Equifax reported 11% revenue growth in its latest quarter. Experian reported 7% organic growth in its latest quarter after an FY26 in which benchmark EBIT rose 15%. TransUnion reported 15% revenue growth, or 10% organically at constant currency.
Yet the public markets have been much less enthusiastic about the sector over the past year. It is tempting to fold that into the broader “SaaS-pocalypse” discussion and conclude that AI is starting to eat away at another established information business.
I think that is too simple. There are too many other things going on. FICO’s October 2025 decision to allow mortgage resellers to license its scores directly, bypassing the traditional bureau distribution path, is one very tangible example.
It triggered an immediate sell-off across the three bureaux. FICO is also a useful reminder of something more fundamental. The bureaux owned the underlying credit files.
FICO came to own a highly valuable layer of interpretation above those files. Owning important data does not automatically mean owning all of the economics built on top of it. That is why the current contradiction is worth exploring.
Is AI making the credit bureau easier to replace? Or does an AI-led credit market make the best bureau data, analytics and infrastructure more valuable? My view is that both things can be true.
AI should technically make parts of the bureau ecosystem easier to switch. It may also make the strongest parts considerably harder to replace.
AI needs data
Much of the early AI discussion has blurred data and software together as sources of competitive advantage, but they are not the same thing.
Software is becoming easier to build. Code can be generated. APIs can be mapped. Documents can be parsed. Data can be transformed. Analytical workflows that once required a meaningful development team can increasingly be assembled much faster and at lower cost. That is bad news for any business whose moat rests mainly on the difficulty of recreating its software or integrating with it.
But AI cannot legitimately infer an external liability that has never been disclosed to it. It cannot reconstruct twenty years of observed repayment outcomes that it has never seen. A bank cannot work out how a business pays suppliers across the economy by looking only at the transaction account it holds itself.
And a plausible AI-generated answer is not the same thing as a documented financial record. This distinction is already visible across the broader data industry. S&P Global has introduced Adaptive Retrieval, which allows AI systems to explore licensed datasets using natural language, alongside Deterministic Retrieval for direct, reproducible access to specific data.
Dun & Bradstreet is doing something similar with its Commercial Graph, making verified business identity, ownership and credit information easier for AI systems to call directly. The point is not the product names. It is the direction of travel.
Good data businesses are making trusted data easier for machines to use. That turns the usual disruption argument around: AI may commoditise some of the software used to analyse information while increasing the value of information that is authoritative, structured, governed and ready to use. That does not mean every bureau suddenly has an “AI data moat”.
Quite the opposite. AI should make public and widely purchasable information easier to collect, reconcile and package. The underlying data still has to be genuinely difficult to reproduce.
The distinction will increasingly be between bureaux that possess differentiated data networks and bureaux that simply possess databases, alongside external registry connectivity.
The bureau moat is really three moats
It helps to separate the bureau franchise into three parts because AI affects each differently.
The first is the data itself.
At its best, a bureau has information the credit provider cannot independently see: external liabilities, applications, repayment performance at other institutions, trade-payment behaviour, insolvencies, linked entities, fraud relationships and years of observed outcomes. The distinctive capability is not one record. It is the ability to bring many records together around the right person or business, with common definitions, history, provenance and mechanisms for correction and use.
None of that makes bureau data perfect. There are errors, matching problems, reporting lags and gaps. But breadth still matters, and so does knowing where the information came from and having enough history to understand and predict what happened next.
The second moat is integration.
Bureau data is embedded in origination systems, decision engines, fraud processes, collections, monitoring, account management and batch workflows. Historically, replacing those connections could be expensive and slow enough to create a real switching cost. AI can enable more competitive tension in this layer.
Schema mapping, API development, code generation, variable substitution, testing and historical replay should all get cheaper and faster. It becomes more realistic for a lender to maintain its own provider-neutral data model and test competing sources without rebuilding everything around them. However, technical switching is not the same as institutional switching.
Change a bureau variable, score or underlying file, and you may change who gets approved, what limit they receive, how they are priced and ultimately what losses emerge. Model validation, governance and policy approval do not disappear because the integration work got easier. AI is likely to make bureau switching technically easier, well before it makes the credit risk of switching any easier to manage.
The third moat is embedded decisioning.
Bureau attributes and scores sit inside approval rules, cut-offs, pricing, fraud, affordability, collections, account management and regulatory documentation. This is often a stronger form of stickiness than an API connection because changing the input can change the customer outcome. FICO showed how valuable this layer can become.
The historical lesson is not that every score becomes FICO. It is simply that a data owner can still lose economic control if another party comes to own the interpretation standard above the data.
Credit bureaux have a head start
The strongest case for the industry is not that credit bureaux can learn to become technology companies. They are already native data, analytics and technology companies. A modern bureau combines data collection, entity and identity matching, analytics, scoring, model development, governance, distribution and decision integration.
Much of that capability now sits on cloud platforms, improving speed, flexibility and the ability to reuse data and analytics across products. The bureau’s traditional job has been to turn individual records into repeatable outputs: attributes, scores, fraud indicators, verification results, alerts and decision services. Once built and deployed, those products can operate at enormous scale and low marginal cost.
AI is adjacent to capabilities bureaux have been developing for decades. Equifax describes proprietary data as the foundation of its AI strategy and reported a 16% New Product Vitality Index for Q2, measuring the revenue contribution from products launched in the past three years.
TransUnion is already using an AI Analytics Orchestrator to speed up advanced credit analytics and extend its analytical capability to more customers. TransUnion has also argued that AI-enabled customers consume more data and adopt new products faster, including an example of a large card issuer moving from periodic checks towards daily engagement and risk triggers. None of that proves AI will expand bureau economics, but the opportunity is reasonably clear.
The incremental value of external data has never been the only constraint on bureau growth. Customer capacity has mattered too: the resources available to analytically assess and implement a new product, development backlogs, integration costs, change windows and capital budgets. If AI materially reduces those constraints, bureaux may find it easier to turn the data and analytics they already possess into greater customer utility.
That is an important advantage. A software company still needs to source the facts its intelligence runs on. A lender knows its own customer deeply but sees only part of the customer’s external financial life. A consulting firm has expertise but struggles to distribute it at software economics.
A strong bureau begins with data, analytics, distribution and customer integration already in place. Becoming more AI-enabled is a smaller step than building those foundations from scratch.
From SaaS to AI routines: commercial credit may be the test case
Bureaux have always tried to move closer to the customer decision. They expanded the data network through more contributors and more data types. They also expanded into value adds: scores, attributes, fraud, identity, decisioning, collections, monitoring, consulting and workflow tools.
The logic is straightforward: the closer you are to the decision, the greater the potential value capture and the deeper the customer relationship. The problem is that workflow expansion often requires a bureau to behave like a SaaS company - build the interface, configure the rules, create the dashboard, manage the case workflow, maintain a full application environment. That is not necessarily where a bureau’s natural advantage or DNA is strongest.
Its strengths are more likely to be data, risk, analytics, models and domain knowledge than general-purpose application software and UX. AI may provide a different route. Commercial credit is a good example because so much of the process still sits between data and a final decision.
An underwriter may need to identify the correct entity, map directors and related companies, review financials and cash flow, consider trade-payment behaviour, check insolvency and security interests, apply policy, document exceptions and prepare a credit paper. Many of those steps have historically been human or semi-manual services. They were already moving towards automation.
AI can accelerate the process and, importantly, could turn parts of the service workflow into a repeatable routine.
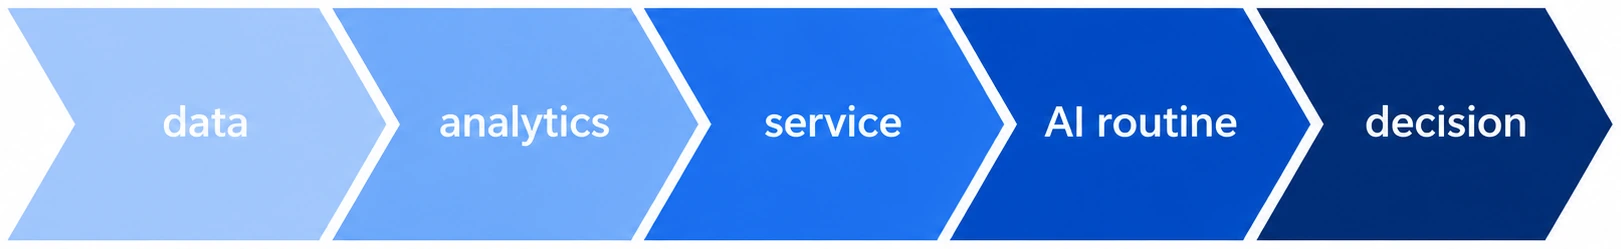
Rather than:
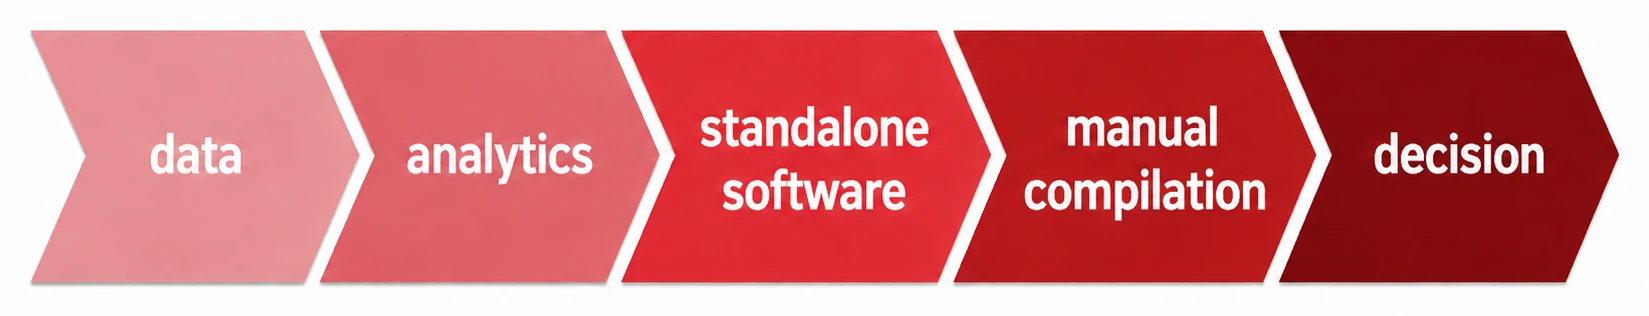
That distinction matters. A bureau may not need to own every screen the credit underwriter uses. It may be enough to own a highly trusted routine inside someone else’s workflow: research this business, reconcile these entities, spread these financials, explain this change in payment behaviour, test this application against policy, monitor this portfolio for deterioration.
This is also why commercial credit may offer more upside than consumer credit. Consumer lending has used scorecards, standardised applications and automated decisioning for decades. Commercial and SME lending still often contains significant document interpretation, financial spreading, entity research, exception handling and human judgement.
Business finance also solves a wider range of problems - working capital, equipment, receivables, inventory, trade credit, merchant finance and supply-chain funding, creating more room for specialised products and decision routines. In more mature markets, commercial lending also has more product innovation and design flexibility than highly regulated consumer credit, although that comes with higher risk, funding and capital considerations rather than just a free regulatory pass.
It is also worth looking at SME credit through a development-market lens. Small businesses account for around 90% of businesses globally and more than half of employment, and SME credit reporting has long been an important part of credit-infrastructure development in emerging markets. In developed economies, the long-established sole-trader market is now being joined by a growing platform and gig economy, further blurring the boundary between consumer and commercial credit. Traditional credit-reporting structures have never fitted this segment particularly neatly.
Combining personal credit, business identity and cash-flow information is another problem AI should make easier to solve. There is one obvious warning for commercial bureaux. A commercial proposition that relies heavily on repackaging company registry information is much more exposed than a strong contributed data network.
AI is very good at finding, extracting and reconciling public information. A lender or specialist platform may increasingly decide it can do that part itself. AI is much less able to recreate information that exists only because a genuine bureau network has collected it: cross-business payment history, contributed defaults, external exposures or historical outcomes.
In commercial credit, the difference between a database and a data network may become very visible.
The counterattack: lenders have AI too
Internal replacement is not new. Banks and lenders have always had transaction histories, balances, repayment performance, applications, collections experience, product holdings and customer tenure. The challenge has been turning all of that first-party information into consistent underwriting signals.
AI and data access lower that cost. The clearest examples are in platform-based business lending. Square assesses eligibility using payment-processing volume, account history and payment frequency.
Stripe uses processing volume and history on its platform. Shopify uses sales performance and other operating signals in its automated underwriting. These businesses have something the bureau does not: a live, proprietary view of activity inside their own ecosystem.
For an existing merchant, that is powerful. But deep is not the same as broad. A bank or payment platform can know a customer extremely well inside its own walls, but its first-party data alone still does not show borrowing elsewhere, trade payments, external security interests, directors’ other businesses, insolvency events or deterioration occurring outside its network.
That is why the likely model in many cases is not transaction data or bureau data. It is transaction data plus external bureau context. Experian’s Cashflow Score is a useful example of the direction: permissioned banking transactions can be used alongside conventional credit information rather than treating one as a complete replacement for the other.
The threat to bureaux is therefore more subtle than wholesale substitution. AI could reduce how often a lender needs a full bureau report. It can make attribute-level calls more practical.
It can help a lender decide when external verification is necessary and when its own information is enough. And it can make it easier to compare different providers for different pieces of data. That could reduce volume and pricing power even where the bureau itself remains important.
Reciprocity is the real test of the data moat
This brings the argument back to a basic question: why does the bureau have the information in the first place? The strongest bureau models are reciprocal. Participants contribute information in return for access to the wider contributed dataset.
The customer is not simply buying the data network; it is helping create it. The often-heard complaint - “I’m paying to buy my own data back from you” - is an oversimplification. The reciprocity model is operationalised through the bureau’s ability to compile the data: accurately match to an entity, connect the relevant records, and return the wider data, scores and attributes that no single contributor holds on its own.
World Bank work on credit-reporting systems has long recognised systematic information exchange and reciprocity as core features of effective bureau models. That is strategically different from a bureau buying public or commercially available information and reselling the aggregation. AI should make that difference more important.
If the information is public or broadly purchasable, it will become easier for competitors and large customers to collect and combine it themselves. If access to a unique cross-institution dataset depends on contribution, participation rules and an established network, it remains much harder to recreate. Reciprocity is not a perfect measure of defensibility.
Large contributors have bargaining power. Coverage varies by segment and rules differ. But once contribution standards and incentives have been weakened, they can be very difficult to rebuild retrospectively.
A bureau whose customers continually replenish a dataset from which they collectively derive value has fundamentally different economics from one that is mainly reselling information available elsewhere.
More reports - or more decisions?
The final question is what happens to bureau demand itself. Historically, we have tended to think in enquiries: an application occurs, a bureau file or score is called, and a data payload is delivered. Over time, AI could compress that model.
A lender may reuse first-party information, make a smaller attribute call, prequalify internally or decide dynamically whether an external check is worth paying for. At the same time, AI can create many more decision points. A large share of credit activity in mature markets is not new-to-credit growth; it is customers refinancing, switching, seeking additional products or being reviewed again.
That recurring churn has always been core to the quality of bureau revenue streams. AI can add another layer - prequalification can become continuous, portfolios can be monitored more frequently, limits can be adjusted as conditions change, and fraud & identity checks can happen repeatedly.
A customer who once generated a bureau event at application may generate multiple risk and monitoring decisions over the life of the relationship. TransUnion’s example of moving a large card issuer from periodic checks towards daily triggers points in exactly this direction. So the future commercial unit may not always be “one bureau enquiry”.
It may increasingly be a decision event, an attribute call or a monitoring trigger. Whether commercial models evolve accordingly, and whether increased decision velocity more than offsets any compression in traditional enquiries, is not yet knowable. But judging future bureau demand only through the lens of today’s report volumes is likely to miss part of the opportunity.
Easier to switch, harder to replace
So does AI strengthen the credit bureau moat or weaken it? For the strongest bureaux, probably both. AI should make technical integration cheaper.
It reduces the protection offered by generic software and makes public information easier to collect and combine. It gives sophisticated lenders much more capability to use their own data. It should also make multi-bureau testing and selective sourcing easier.
Those are real threats. But AI also increases the usefulness of clean, structured external data. Automated decisions still need to know which entity they are dealing with, where the information came from, how current it is and what happened historically.
Most importantly, they still benefit from information the customer or lender cannot independently observe. The result may be a much bigger gap between strong and weak bureaux. Bureaux whose moat is mainly integration friction, generic workflow software or reproducible data will likely be more exposed.
Bureaux with strong reciprocal networks, differentiated external information, good identifiers, deep history, and the capability to turn that data into repeatable analytical routines may become more valuable. The strategy is not to defend the traditional report at all costs. It is to protect the data network, make that information easy for new decision systems to use, and keep moving closer to the customer decision where the bureau has something distinctive to contribute.
The credit bureau model has been theoretically challenged plenty of times by new data sets and tech. The model has endured many cycles, and well-run bureaux remain productive growth assets.
It looks like another iteration of where the value is captured. A good bureau may become easier to switch from technically at the same time it becomes harder to replace economically.
References and further reading
- Equifax: Second Quarter 2026 Results, 21 July 2026. Revenue, organic growth and adjusted EBITDA performance.
- TransUnion: Second Quarter 2026 Results, 28 July 2026. Revenue, organic constant-currency growth and adjusted EBITDA performance.
- Experian: Trading Update, First Quarter FY27, 16 July 2026. Q1 organic and total revenue growth.
- Experian: Full-Year Results FY26, 20 May 2026. FY26 organic growth, benchmark EBIT growth, margin performance, productivity and technology investment.
- FICO: FICO Mortgage Direct License Program, 1 October 2025. Direct licensing of FICO Scores to tri-merge mortgage resellers and changes to bureau distribution economics.
- Reuters: FICO direct licensing and credit-bureau share-price reaction, 2 October 2025.
- S&P Global: Adaptive Retrieval, 21 July 2026. AI and agentic access to multiple licensed datasets.
- S&P Global: Deterministic Retrieval, July 2026. Reproducible API-driven access to licensed S&P Global data for AI workflows.
- Dun & Bradstreet: AI Connectors and Commercial Graph. MCP-based access allowing AI systems to retrieve governed business identity, ownership, risk and commercial information.
- TransUnion: AI Analytics Orchestrator Agent, 5 March 2026. Use of AI to automate governed credit analytics and reduce analytical cycle times.
- TransUnion: First Quarter 2026 Investor Presentation, 28 April 2026. AI-enabled customer data consumption, daily risk triggers and the 50m+ account card-issuer example.
- Equifax: Equifax Cloud / EFX.AI. Technology transformation supporting data management, analytics, models and AI-enabled products.
- TransUnion: OneTru technology platform. Cloud-enabled data management, identity resolution, analytics and governed delivery.
- Experian: FY26 Results Presentation. Cloud migration, AI-enabled productivity and growth in data and analytics.
- Square Australia: Square Loans eligibility requirements. Use of payment-processing volume, account history and payment frequency in lending eligibility.
- Stripe: How Stripe Capital works. Use of processing volume and history on its platform in financing eligibility and underwriting.
- Shopify: Shopify Capital eligibility. Use of sales performance and operating activity in automated underwriting.
- Experian: Cashflow Score. Consumer-permissioned banking transaction data used alongside or independently of traditional credit information.
- World Bank: General Principles for Credit Reporting. Framework for systematic credit-information exchange, governance and credit-reporting systems.
- World Bank: Credit Reporting Knowledge Guide. Credit-bureau development, reciprocity and SME credit reporting.
- World Bank: SME Finance. Economic significance of SMEs globally.
- Australian Securities and Investments Commission: Does the credit legislation apply? Scope of the National Credit Act in relation to consumer and commercial-purpose lending.
- Australian Securities and Investments Commission: National Credit Code. Application of Australia’s consumer-credit regime and its purpose tests.